 |
Peano
|
|
Peano
|
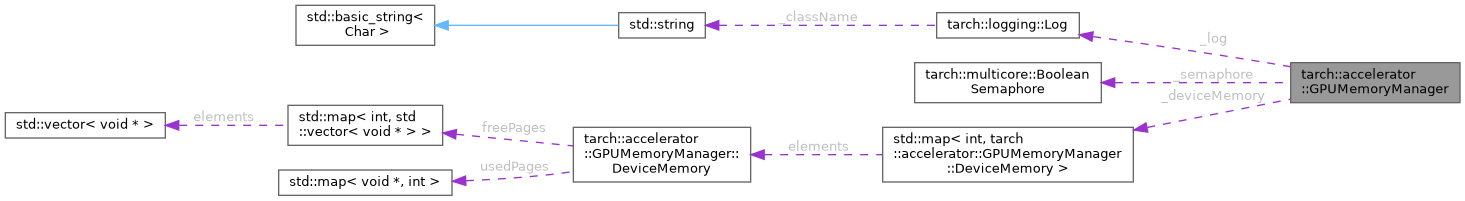
Singleton that manages persistent memory on the GPUs. More...
#include <GPUMemoryManager.h>
Data Structures | |
| struct | DeviceMemory |
Public Member Functions | |
| GPUMemoryManager (const GPUMemoryManager ©)=delete | |
| virtual | ~GPUMemoryManager () |
| Invoke clear(). | |
| template<class T > | |
| T * | allocate (int size, DeviceType device) |
| void * | allocateRawData (int size, DeviceType device) |
| Return a pointer to new device data of size size bytes on device. | |
| void | free (void *devicePointer, DeviceType device) |
| Free does not actually free data, but instead hands the memory block back to the singleton, such that the next allocateRawData() call can reuse the memory region. | |
| void | clear () |
| Idempotent function. | |
Static Public Member Functions | |
| static GPUMemoryManager & | getInstance () |
Private Types | |
| typedef std::map< int, std::vector< void * > > | FreePages |
| Map of pages (memory blocks) per size. | |
| typedef std::map< void *, int > | UsedPages |
| Counterpart of FreePages, i.e. | |
Private Member Functions | |
| GPUMemoryManager ()=default | |
Private Attributes | |
| tarch::multicore::BooleanSemaphore | _semaphore |
| std::map< int, DeviceMemory > | _deviceMemory |
| Map from device number onto memory. | |
Static Private Attributes | |
| static tarch::logging::Log | _log |
| static int | _allocatedMemory |
| _allocatedMemory and _maxMemory are used to track remaining space on the device. | |
| static constexpr int | _maxMemory = -1 |
Singleton that manages persistent memory on the GPUs.
The idea is that this is basically a heap rep for the GPU and that code requiring GPU memory does not allocate this memory but instead grabs it from here. As it is not freed afterwards, we avoid overheads that arise from frequent re-allocation.
It seems that memory allocation on GPUs is very slow with most OMP runtimes. Therefore, it is reasonable to manage the GPU memory in the user space.
Definition at line 37 of file GPUMemoryManager.h.
|
private |
Map of pages (memory blocks) per size.
Definition at line 53 of file GPUMemoryManager.h.
|
private |
Counterpart of FreePages, i.e.
map of memory blocks (addresses) onto sizes.
Definition at line 59 of file GPUMemoryManager.h.
|
privatedefault |
|
delete |
|
virtual |
Invoke clear().
| T * tarch::accelerator::GPUMemoryManager::allocate | ( | int | size, |
| DeviceType | device | ||
| ) |
| size | Count of block, i.e. number of doubles |
Definition at line 89 of file GPUMemoryManager.h.
References allocateRawData().
| void * tarch::accelerator::GPUMemoryManager::allocateRawData | ( | int | size, |
| DeviceType | device | ||
| ) |
Return a pointer to new device data of size size bytes on device.
This operation is thread-safe. If tries to recycle data that has been allocated before. If this is not successful, it acquires new data on device and then hands out this new data.
Before we return the address of the new data, we memorise it as booked data and store the size corresponding to this device. This is important: When we return the data through free(), we have to look up what the underlying size is and bucket sort the pointer for reusage appropriately.
The routine could, in theory, hand out a pointer to a memory block which points to a chunk of memory that is bigger than size. In the context of Peano this would however be stupid: Most Peano codes work with rather regular chunks of data and if we use big chunks to host smaller data footprint, we actually run risk to fragment the device memory.
To make the allocation efficient, i.e. to avoid too many allocations, we do not acquire one more entry per request, but we immediately acquire several entries. The number of entries that we grab in one rush is given by growth. Many codes acquire data that depends on the Dimensions. Therefore, I use this magic default here.
| growth | Number greater than zero which tells the code how many entries (pages) to book whenever it runs out of memory. |
Referenced by allocate().
| void tarch::accelerator::GPUMemoryManager::clear | ( | ) |
Idempotent function.
Run over _deviceMemory, i.e. handle device by device. If a device still has used pages, the user code has not properly freed data. We issue an error.
This operation is thread-safe.
Referenced by peano4.api.output.Makefile.Makefile::__init__().
| void tarch::accelerator::GPUMemoryManager::free | ( | void * | devicePointer, |
| DeviceType | device | ||
| ) |
Free does not actually free data, but instead hands the memory block back to the singleton, such that the next allocateRawData() call can reuse the memory region.
|
static |
|
staticprivate |
_allocatedMemory and _maxMemory are used to track remaining space on the device.
If _maxMemory is -1 then it is assumed that there is no memory limitation;
Definition at line 45 of file GPUMemoryManager.h.
|
private |
Map from device number onto memory.
Definition at line 69 of file GPUMemoryManager.h.
|
staticprivate |
Definition at line 39 of file GPUMemoryManager.h.
|
staticconstexprprivate |
Definition at line 46 of file GPUMemoryManager.h.
|
private |
Definition at line 48 of file GPUMemoryManager.h.
 1.9.8